Solution
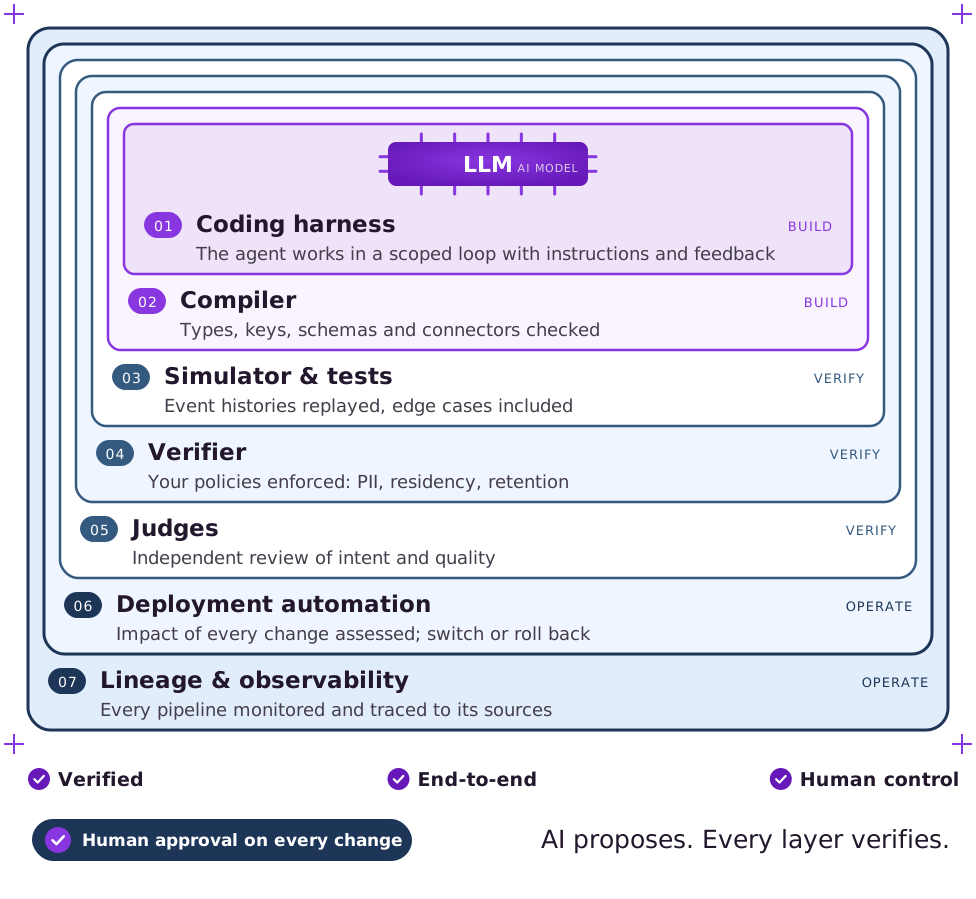
AI proposes.
Every layer verifies.
Agentic data engineering across the whole life of your data products and pipelines. DataSQRL closes the feedback loop, engineers approve every change.
01 / Build and approve
Agent-built. Human-approved.
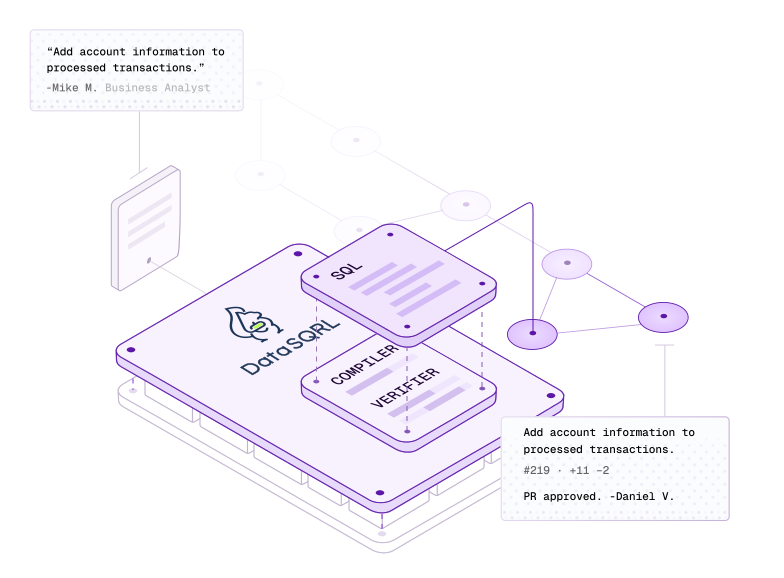
Your coding agent describes the change. DataSQRL turns it into one SQL specification: the single source your team reads and reviews.
- SQL your team already knows, not generated code nobody wants to read.
- Every change arrives as a pull request with its test results and lineage. Trust every deployment.
- Git-native: branches, reviews and CI/CD that fits your workflow.
02 / Verify
Production-grade from the first commit.
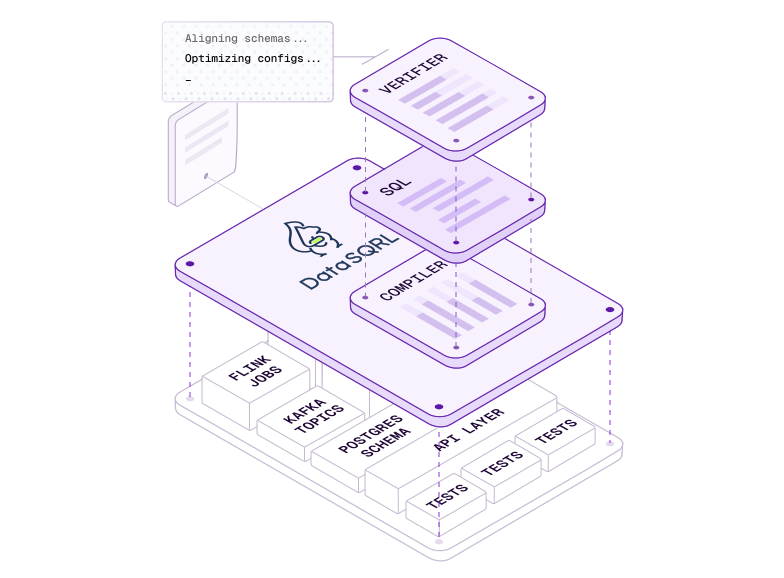
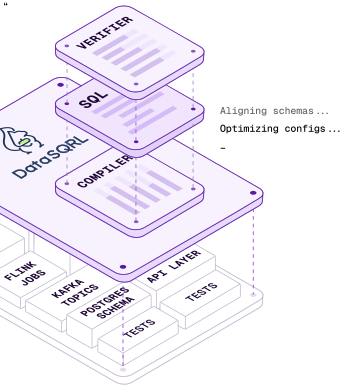
The compiler checks types, keys, schemas and connectors, then builds every deployment asset from the specification.
- Flink jobs, Kafka topics, database schemas, the API layer and tests, all compiled and consistent with each other.
- Validators enforce your policies: PII, residency, retention, naming.
- Real-world tests: the simulator replays event histories at their original timestamps, including late, out-of-order and deleted records.
03 / Deploy
Every rollout analysed. Every rollout reversible.
Before a change goes live, deployment analysis verifies its behaviour. Then blue-green deployment runs the new version beside the current one.
- The new version processes the same data as the live one before it takes any traffic.
- Switch over when the results match; roll back in one step if they do not.
- No big-bang releases, no maintenance windows for routine changes.
Deployment analysis · change #219
- Affects
RiskScores, /api/risk - API
No breaking changes - Replay
30 days, late records included
Blue · v41
Live, serving
Green · v42
✓Results match v41
04 / Operate and maintain
Runs itself. Fixes itself. Answers to your engineers.
DataSQRL keeps a record of every pipeline it runs: monitoring, alerting, lineage, schemas and data-flow metadata.
- Every value traces back to its sources; every pipeline has its metrics and its history.
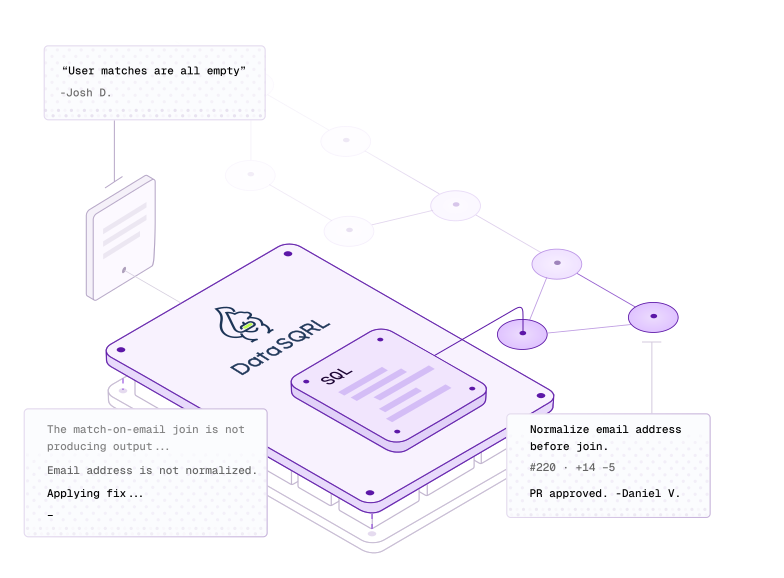
- The agent troubleshoots data inconsistencies based on runtime telemetry and proposes fixes.
- The same verification and the same approval apply to every fix. The loop closes.
05 / Your workflow
Plugs into the agent your team already uses.
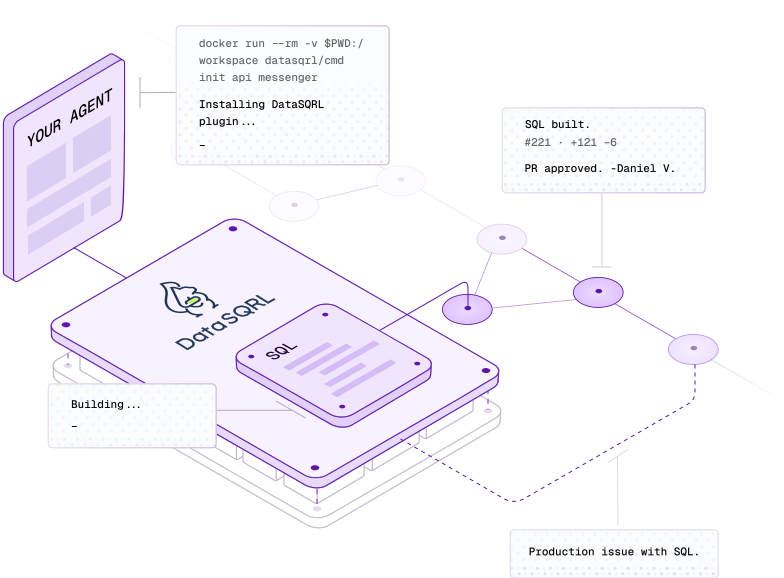
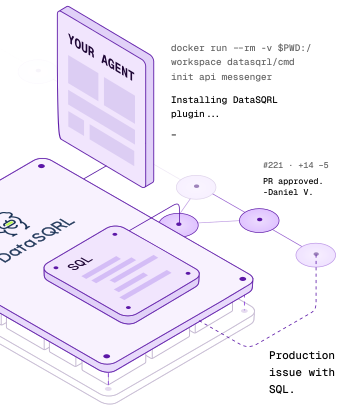
Your coding agent gets a data engineering sidekick: it builds, verifies and opens a pull request your team reviews like any other change. When something breaks in production, it comes back through the same loop.
06 / Architecture
One specification, compiled to an integrated stack.
Ingestion and processing on Flink, storage on Postgres, Kafka and Iceberg, serving through GraphQL, REST, MCP tools and data products. You select the engines, DataSQRL keeps them consistent.
07 / Fits what you run
Nothing to rip out.
Sources
Existing databases (change data capture), event streams, files, APIs and the output of your ETL.
Destinations
Iceberg tables your warehouse or lakehouse can read, your BI, and APIs and MCP tools for AI applications.
People
SQL, Git and pull requests, your organisation’s coding agent. Fits into your workflow and what your team already knows.
What it is not
Not a data platform, warehouse, proprietary runtime, or black-box AI service. DataSQRL brings these systems together and closes the loop.
08 / Deployment
Data plane in your account. Control plane separate.
Pipelines run in your Kubernetes cluster, in your cloud account or on-premises, under your IAM. Your data never leaves your account.
09 / Open source
Read every line that touches your data.
The core is Apache 2.0 and public. Your architects can inspect the compiler, the simulator and the runtime before the first meeting.
10 / First step
Start with one use case. See it work.
A scoped Proof of Value on a use case you already have, with success criteria agreed before we start.